AFM Tip-Cell Segmentation Pipeline
Automated segmentation pipeline for AFM T-cell images. A probe-aware geometry rule selects the indented cell in crowded frames, scoring 0.813 mean Dice on 39 held-out frames with zero empty outputs. Ablation shows the selection rule contributes +0.65 Dice while model fine-tuning contributes +0.02.
Solo Researcher (Undergraduate) · Fall 2025 · Team of 1 · 3 key work items · 3 evidence-backed
What I owned
Owned the full pipeline end-to-end: dataset curation and quality control, stratified train/test split design, Cellpose fine-tuning, automatic cantilever tip detection, probe-aware cell selection logic, failure handling with structured fallback paths, per-frame QC artifact generation, and a verification framework with per-frame failure logging. Also audited and corrected my own evaluation protocol after finding that the originally reported metrics were computed on a set that included training frames; all numbers here are from a held-out test set under a single global threshold configuration. AFM images provided by graduate researcher at Sulchek Lab (Georgia Tech).
Key Work · 3
Designed probe-aware selection logic to pick the indented cell in crowded frames, and isolated its contribution by ablation
▾The rule is the dominant source of pipeline performance: 0.813 mean Dice with probe-aware selection versus 0.140 with a largest-cell baseline on the identical model and identical 39 held-out frames. Fine-tuning the model moves the same number by 0.024. Zero pred-empty frames across all configurations; one retry fired in 39 frames; every non-normal path flagged and logged.
Fine-tuned Cellpose-SAM on AFM T-cell frames and quantified its marginal contribution against an out-of-box baseline
▾Fine-tuning contributes +0.024 mean Dice on held-out frames (0.813 versus 0.789 for out-of-box Cellpose-SAM under the same selection rule), consistent in direction across subsets but small. The practical implication: the pipeline may be able to run on the base model plus the selection rule, which would remove any need to distribute weights trained on lab data.
Built a per-frame verification framework, then used it to audit and correct my own evaluation protocol
▾The audit found that originally reported metrics (0.889 mean Dice) had been computed over all 216 frames, including the 177 the model trained on, with per-subset thresholds selected by inspecting results on those same frames. Because every run was stamped and every frame logged, the error was reconstructible from stored outputs without re-running inference. The evaluation was re-run held-out under one global configuration and re-reported at 0.813; all public numbers were corrected.
Interfaces
| From | To | Type | Description |
|---|---|---|---|
| Raw AFM frame (.tif) | Preprocessing module | data | Grayscale load + percentile [2,98] intensity normalization; optional contrast normalization and morphological closing per subset config |
| Preprocessing module | Cellpose model | data | Full AFM frame passed without cropping. Corrected evaluation applies a single global cellprob_threshold and flow_threshold to every frame; per-subset overrides were used in the original run and are retained only as a tuned upper bound, not as a deployable configuration. |
| Cellpose model | Probe-aware selection logic | software | Multi-instance integer label map passed to geometry rule; probe coordinates sourced from auto-detector or PROBE_MAP fallback |
| Probe-aware selection logic | QC artifact writer | software | Single binary tip-cell mask + selected instance metadata; path taken (normal, retry, fallback) logged per frame to JSON |
Documents
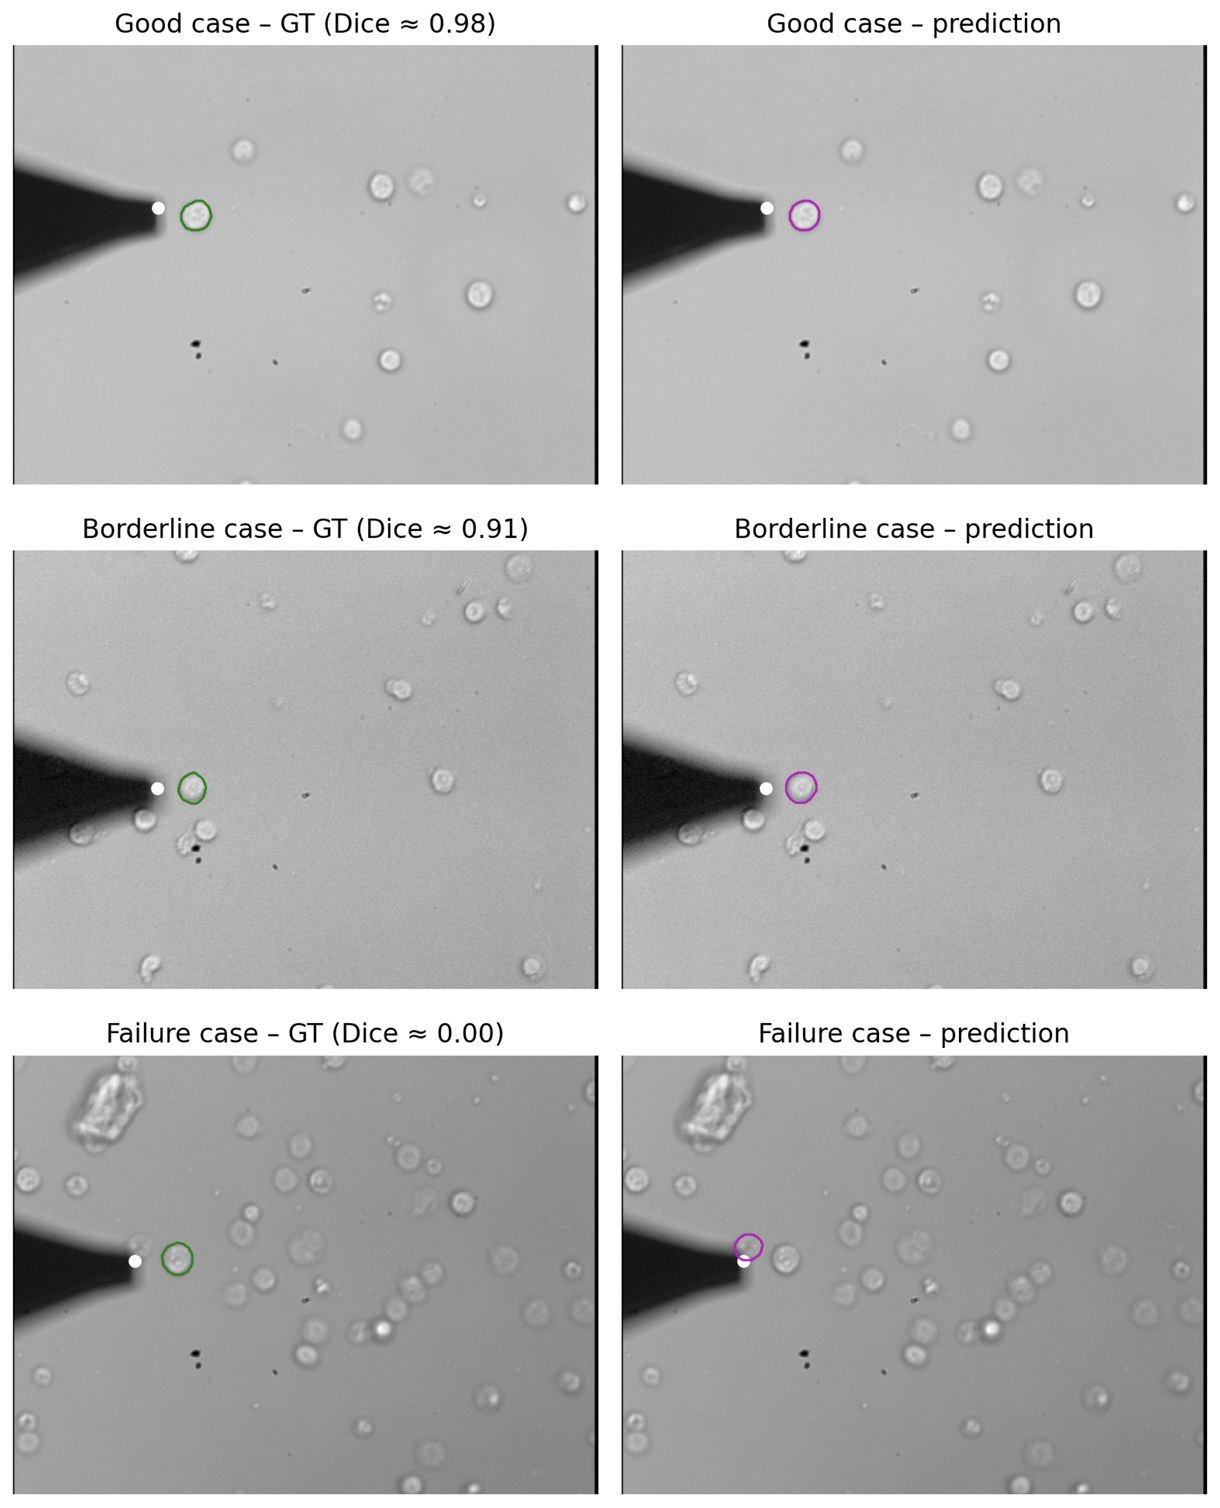
6-panel grid showing ground truth vs predicted masks across three qualitative performance classes
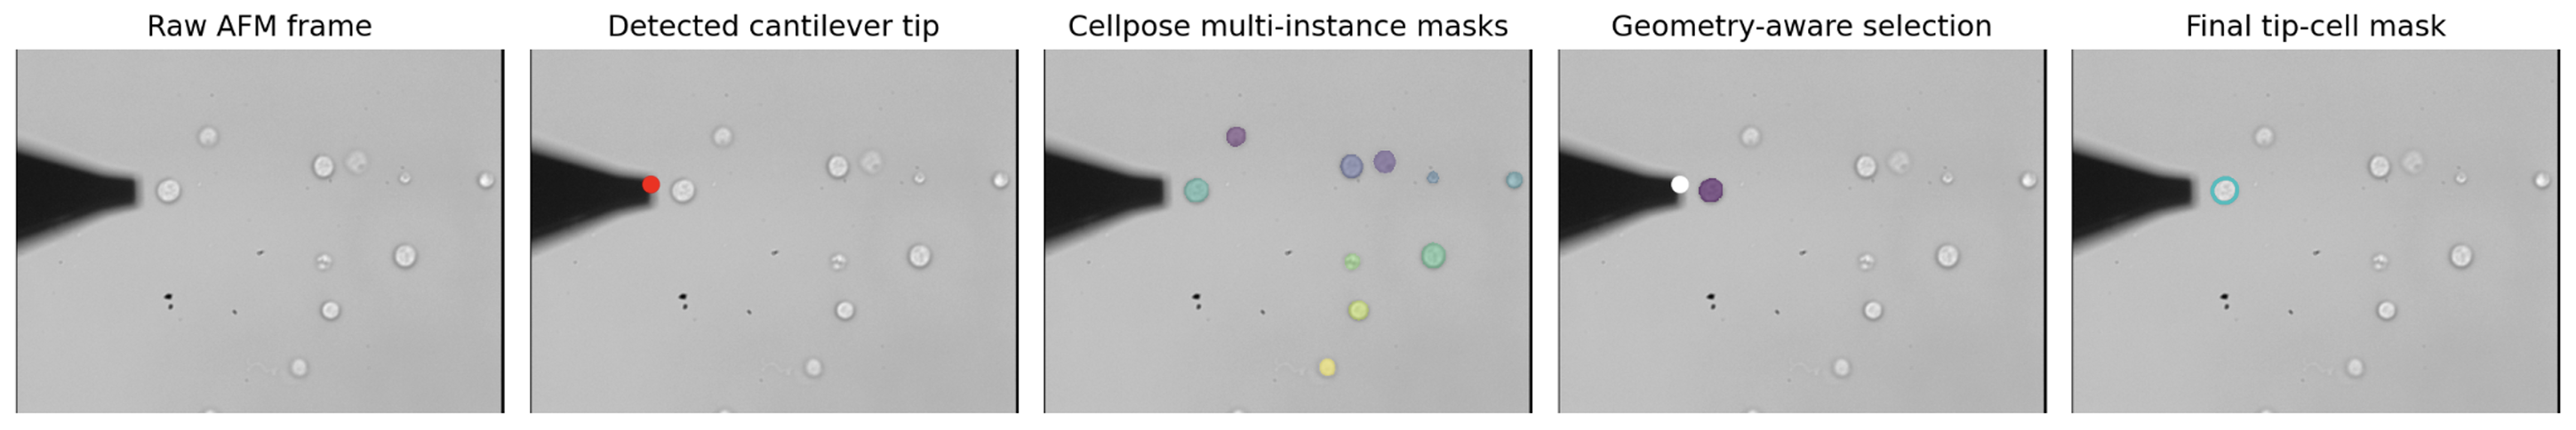
5-panel strip showing each stage: raw AFM frame → detected cantilever tip → Cellpose multi-instance masks → geometry-aware selection → final tip-cell mask
Limitations
- • DN1-rate is the measured failure domain: 0.275 mean Dice on held-out frames (n=4) under global thresholds, against approximately 0.87 for the remaining 35. This subset carried the heaviest per-subset threshold overrides in the original configuration, so its difficulty was previously masked rather than solved.
- • Performance without per-subset tuning is now measured rather than estimated. Under one global configuration the pipeline holds up on seven of eight subsets and fails on the eighth. Generalization to a new imaging session or microscope remains uncharacterized; no data outside this dataset has been tested.
- • Auto tip detection relies on a static rightmost-point heuristic and assumes the cantilever is darker than the background. Performance is consistent for DN2–DN4 but degrades on DN1 and would fail if cantilever geometry changed significantly.
- • Held-out n is 39 frames, four to five per subset. Subset-level numbers move substantially with a single frame and should be read as indicative, not precise.
Lessons
- In preparing this work for external review, I found that my originally reported metrics had been computed over the full dataset rather than the held-out split, so 177 of 216 scored frames were training data, and that per-subset thresholds had been selected by inspecting results on those same frames. I re-ran the evaluation on the 39 held-out frames under one global configuration and re-reported. The honest number is roughly 0.08 lower. Catching this myself, before anyone else relied on it, mattered more than the number did.
- The dominant failure mode was cell selection, not segmentation — the model segmented correctly but chose the wrong cell. Identifying this shifted the design direction from backbone improvement to geometry-aware post-processing.
- Per-frame path logging (normal, retry, fallback) made failure patterns immediately diagnosable without re-running inference. Structured logging is what separates a debuggable pipeline from a black box.
- Per-subset threshold overrides are a structural workaround, and the ablation put a number on the cost: removing them exposes one subset that drops to 0.275 Dice. The overrides were compensating for a model with no domain understanding rather than fixing it. Domain conditioning or geometry-aware training is the correct architecture, not more manual knobs.
- The ablation redirected what I would build next. Fine-tuning contributed +0.02 and the geometry rule contributed +0.65, which means effort belongs in selection and domain conditioning, not in the backbone. It also implies the pipeline may run on out-of-box Cellpose plus the rule, which would remove the need to distribute weights trained on lab data.